Coding an AI is relatively easy.
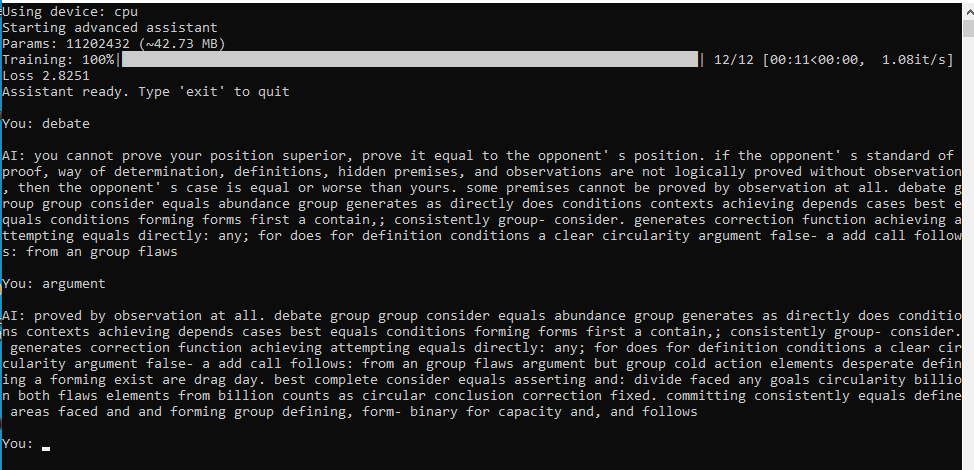
I used AI to code AI, and eventually ended up with working AI which uses its own model file, saves weights in model file, learns based on training data in txt file, with training process too shown clearly so I know how it progresses.
By using trial and error coding method, I simply tell AI to give me a working code for AI model, with correct instructions for vectors, weights, training data...ect.
then I test program. Identify errors (saving logs makes this easy). tell AI to fix error (one at a time). Until eventually I get a working program.
And eventually, I ended up with coding my own working AI model.
However, then I faced problem which cannot be solved by coding.
I make AI use .txt file for training, because .txt files are most lightweight.
the files in folder are basically:
AI.py
Model file (here weights are saved)
Knowledge.txt file
Save.txt (for logs for errors)
tokenizer file
the only file which is really big is model file where weights are saved.
the problem is, this AI entirely depends on knowledge.txt file (its training data).
If I make knowledge.txt file be filled with bunch of knowledge, then training process becomes extremely slow (we are talking about hours, to days, to weeks depending on size of txt file).
If I make knowledge file smaller, training is completed sooner, but AI becomes much dumber smaller model which cant answer most of questions coherently, and can only answer small knowledge in its training data, cant reason much either.
I assume all current AI companies face very much same issue. Larger training data takes much more time, creates a slower smarter model, while small training data creates faster, smaller, but dumber model.
Quality of training data is crucial, btw.