There is also no number two times smaller than zero.
There is also no number two times smaller than zero.
any mass is greater than no mass
Mathematically, no. Mass of 2 is not greater than mass of zero. If it truly were greater, we would know how many times greater.
But sadly, there is no number two times greater than zero.
Mathematically, there is no such number
So no number is greater than zero. Math doesn't work.
Which number is two times greater than zero?
Well, I think you are smarter than AI.
It's easy to be smarter than AI. However, it's a bit difficult to teach AI to be as smart as me. I mean, not even chatgpt can keep up.
Both are secretly reptiles and lizards who come from secret underground cities.
If you see a politician in USA, there is 90% change he got replaced by a shapeshifter.
Sadly, my laptop's maximum reasonable performance is 4096 context and 8 batch size.
It doesn't really get higher than that no matter how much I reduce the parameters.
I can also run with 256 context and 128 batch size, so that speeds up training, but 256 context size isn't really a great number. It's only 256 words. My AI might become a bit dumb.
Socialism is really modern feudalism with the nobility in government
Nobility is always in government. What do you think the government is made of? Plebs? Bee workers?
No, plebs are never part of government. That's why they are called plebs. Any system which promises a pleb that he will be part of government is just making fun of his stupidity.
What he meant is that we are actually living in pre-human history right now because our existence is not guaranteed
Meowbah already refuted Socialism.
"Meow was hungry, and you gave Meow something to eat. Meow was thirsty and you gave Meow something to drink. And behold, now Meow is all lazy and entitled. You shouldn't have done that."
There is no such thing as a "human history". Reality is, all history involves sacrificing a part of population so that others can live. Best example of this are cars. A lot of people die in car accidents so that others may have cars. It's called modern human sacrifice. Sacrificing some so that others can live or be entertained by the very system which kills others.
There is no such thing as peace. The punishment for incompetence is misery and often death too. This is why I don't go outside. I don't want to be punished.
I think I lost 20 IQ points reading that retarded shit
That still leaves you with about 300 IQ.
Oh yeah, tho I am trying to make AI trained on my personal opinions so it doesn't suffer from bias.
So far what seems good is 4096 context and 8 batch size, on a word level AI, these make training really fast. And larger context might even make AI slightly smarter.
you notice how they don't deny being for things like open borders and transing your children
Not all children are trans, just 1% are. So 99% of voters are safe.
trying to use logic in a conversation with someone advocating for magic does seem pretty pointless.
It's also circular reasoning, because you are using logic to argue for logic.
the rest of us will get back to dealing with reality
I don't believe in reality. I believe in Meow-logic.
I also discovered that if you reduce batch size to 1, you can greatly increase context size. Tho increasing context size to 8000 words (in case of word level AI) doesnt work if your training data is less than 16000 words. It means only two batches, and makes training awkward because loss function of two batches tends to be different. You realistically need at least 4 batches to have good enough training.
What you’re actually calling meow logic now isn’t logic at all, it’s just unsubstantiated hand waiving
Meow-logic isn't logic. I already told you. It's magic. It has nothing to do with logic. Logic is a failure, where Meow-logic is success.
Also, if I were you, I wouldn't use logic to attack Meow-logic. It seems like quite a pointless thing to do, even circular reasoning.
In other words, you used logic to argue against logic.
No, I used Meow-logic to argue against logic.
Logic is the process by which we arrive at conclusions from given a set of premises.
Unproved claim.
I have this same version of code for word level AI. I call him "the big guy". Cuz he is much bigger than character level AI and trains much faster too, while having much bigger context window. Of course, word level AI has its disadvantages too, but those disadvantages are mainly about being completely incapable of dealing with unknown words and spelling errors of user. For example, if you typed he!!o instead of hello, it wouldn't know that you are saying hello to him. Big guy is a bit dumb in that area.
I have never understood people saying they don't wanna have kids because of the cost
Idk, some people also like to have free time.
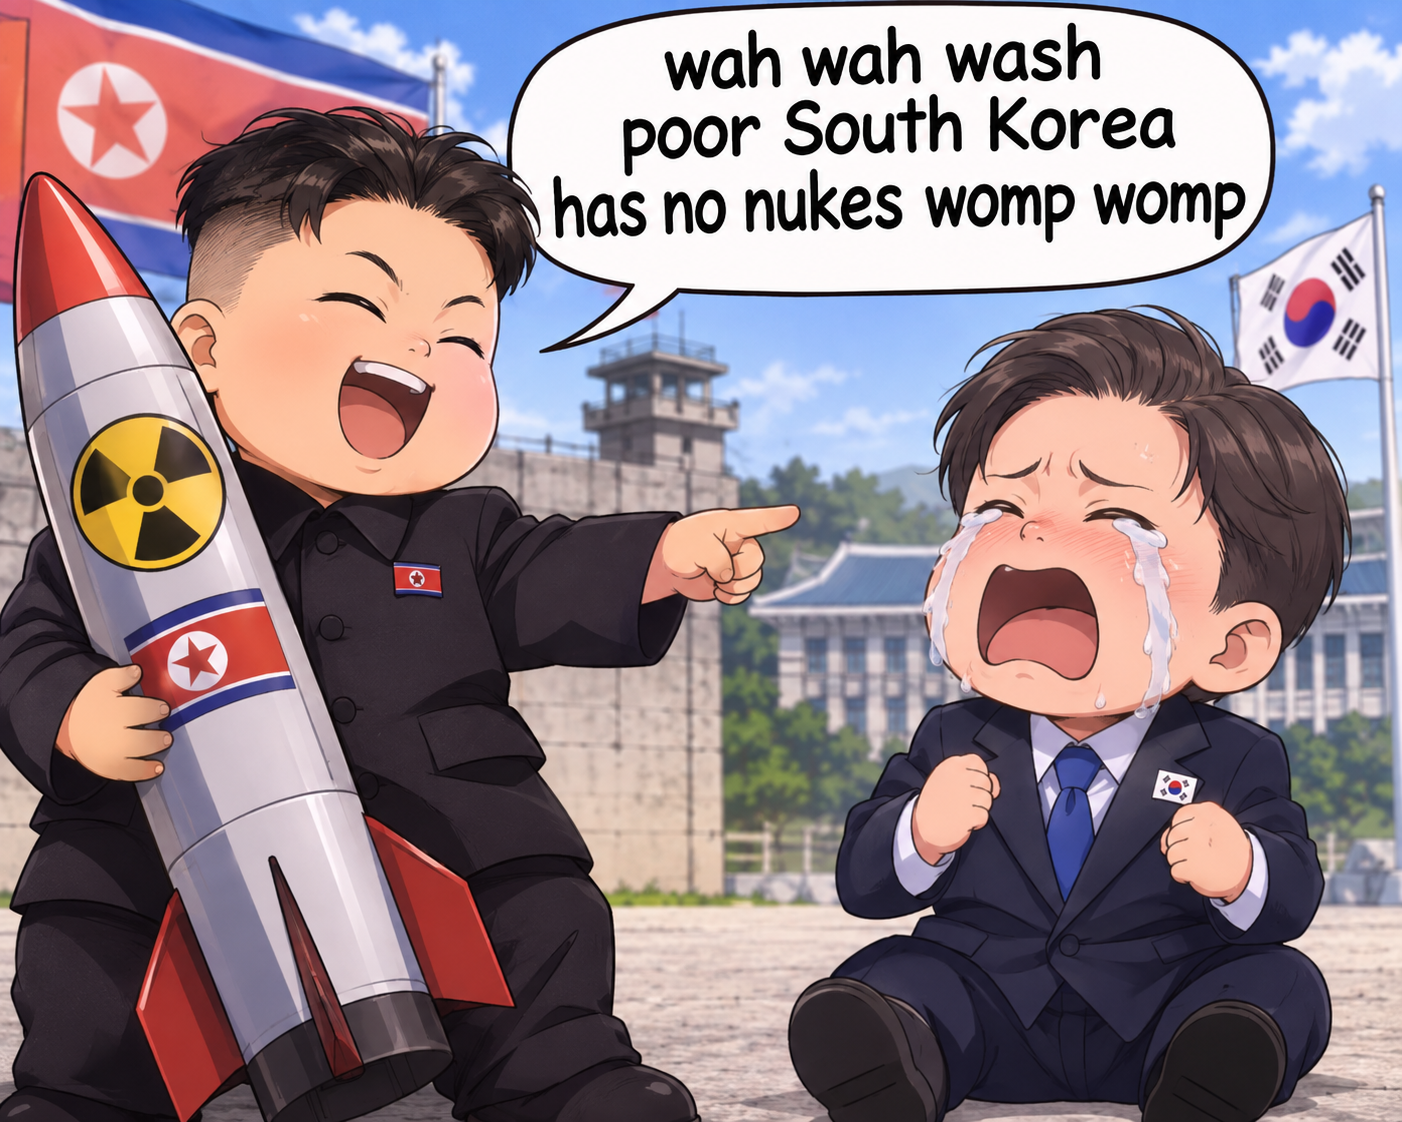
North Korea is modern Sparta. Talk about a country of merely 26 million people. Most countries of that size don't even have a nuke. Can you imagine not having a nuke in 21st century? South Korea can.
Poor South Korea cry wah wah no nukes :(
AI needs less correction than your posts
Actually AI needs bunch of corrections. In fact, training itself is correcting AI weighs all the time.
When I make a new AI model, it just makes baby words like "bah ah wah".
It takes a lot of training and good training data and corrections to get anything out of AI.
There are a few improvements I made for this code, but two are major ones.
First is, I removed overlapping batches. I used to think overlapping batches are good for training, but they make training time 300 times longer and this becomes very unpractical for large texts.
Second is, I introduced epoch per batch, so AI for example trains 10 times on one batch before moving to next one.
If you wonder if God likes you, you can do this test:
A. Were you born rich?
B. Did your father give you a "small loan" of 1 million dollars?
C. Did you marry a slovenian sex worker?
D. Did you become president of USA twice?
E. Did you create a MAGA cult of followers who believe all you say even when you are lying non-stop?
F. Did you commit every crime there is and still didnt go to prison?
G. Are you a billionaire?
H. Did you inherit a fortune?
I. Did you fuck countless women, some even married?
J. Did you break every promise you made and still had millions believe you?
These questions should tell you if God loves you or not.
Looks fine I guess. Although with AI code now, the bar for super impressive code is higher.
Well, this code was made by AI. Admittedly, after many mistakes AI made. I tried to keep code as short as possible, and AI was adding things I didnt tell it to add.
Setting temperature to 0.1 means AI almost never makes mistakes, but it also means less creativity. I managed to train it on merely 10 kb text size, and it has succeeded in repeating from training data perfectly when temperature was lower. Also, the one I trained was only 0.8 million parameters.
This is where you set AI response size and temperature
max_new_chars=512, temperature=0.8):
I dont want to bother you too much, but what do you think of this code?
This is a code for character level AI.
Code does pretty much everything. It both creates and trains AI model, and enables chatting with AI model.
It lets you set how many parameters do you want in your AI model.
This AI can be trained on any data as small as 10 kb in size.
LEARNING_RATE is set at 0.000001, but that is for fine tuning. Normally you start with 0.0001.
The only thing a code needs is knowledge.txt file which is where you put text you want AI to learn.
Once loss reaches 0.05, it has pretty much learned text well.
Code is fully adjustable. You can adjust how many epoches, context size, batch size, anything. It works on both GPU and CPU.
import os
import json
import math
import torch
import torch.nn as nn
import torch.nn.functional as F
from torch.utils.data import Dataset, DataLoader
# =========================
# SETTINGS
# =========================
KNOWLEDGE_FILE = "knowledge.txt"
MODEL_FILE = "model.pt"
VOCAB_FILE = "vocab.json"
OPTIMIZER_FILE = "optimizer.pt"
BATCH_SIZE = 128
CONTEXT_SIZE = 128
EPOCHS_PER_RUN = 50
LEARNING_RATE = 0.000001
DEVICE = torch.device("cuda" if torch.cuda.is_available() else "cpu")
# ~1 million parameter model
EMBED_SIZE = 128
NUM_HEADS = 4
NUM_LAYERS = 4
FF_SIZE = 512
# =========================
# TOKENIZER
# =========================
def build_vocab(text):
chars = sorted(list(set(text)))
stoi = {ch: i for i, ch in enumerate(chars)}
itos = {i: ch for i, ch in enumerate(chars)}
return stoi, itos
def save_vocab(stoi):
with open(VOCAB_FILE, "w", encoding="utf-8") as f:
json.dump(stoi, f)
def load_vocab():
with open(VOCAB_FILE, "r", encoding="utf-8") as f:
stoi = json.load(f)
itos = {int(v): k for k, v in zip(stoi.keys(), stoi.values())}
return stoi, itos
# =========================
# DATASET
# =========================
class CharDataset(Dataset):
def __init__(self, data, block_size):
self.data = data
self.block_size = block_size
def __len__(self):
return len(self.data) - self.block_size - 1
def __getitem__(self, idx):
x = self.data[idx:idx+self.block_size]
y = self.data[idx+1:idx+self.block_size+1]
return torch.tensor(x), torch.tensor(y)
# =========================
# MODEL
# =========================
class GPTBlock(nn.Module):
def __init__(self, embed_size, heads, ff_size):
super().__init__()
self.attn = nn.MultiheadAttention(
embed_size,
heads,
batch_first=True
)
self.ln1 = nn.LayerNorm(embed_size)
self.ln2 = nn.LayerNorm(embed_size)
self.ff = nn.Sequential(
nn.Linear(embed_size, ff_size),
nn.ReLU(),
nn.Linear(ff_size, embed_size)
)
def forward(self, x):
seq_len = x.size(1)
mask = torch.triu(
torch.ones(seq_len, seq_len, device=x.device),
diagonal=1
).bool()
attn_out, _ = self.attn(
x, x, x,
attn_mask=mask
)
x = self.ln1(x + attn_out)
x = self.ln2(x + self.ff(x))
return x
class GPTModel(nn.Module):
def __init__(self, vocab_size):
super().__init__()
self.token_emb = nn.Embedding(vocab_size, EMBED_SIZE)
self.pos_emb = nn.Embedding(CONTEXT_SIZE, EMBED_SIZE)
self.blocks = nn.ModuleList([
GPTBlock(
EMBED_SIZE,
NUM_HEADS,
FF_SIZE
)
for _ in range(NUM_LAYERS)
])
self.ln = nn.LayerNorm(EMBED_SIZE)
self.head = nn.Linear(EMBED_SIZE, vocab_size)
def forward(self, idx):
B, T = idx.shape
tok = self.token_emb(idx)
pos = self.pos_emb(
torch.arange(T, device=idx.device)
)
x = tok + pos
for block in self.blocks:
x = block(x)
x = self.ln(x)
return self.head(x)
# =========================
# PARAMETER COUNT
# =========================
def count_parameters(model):
return sum(
p.numel()
for p in model.parameters()
if p.requires_grad
)
# =========================
# TRAIN
# =========================
def train_epoch(model, loader, optimizer):
model.train()
total_batches = len(loader)
for batch_idx, (x, y) in enumerate(loader):
x = x.to(DEVICE)
y = y.to(DEVICE)
optimizer.zero_grad()
logits = model(x)
loss = F.cross_entropy(
logits.reshape(-1, logits.size(-1)),
y.reshape(-1)
)
loss.backward()
optimizer.step()
percent = (batch_idx + 1) / total_batches * 100
print(
f"\rBatch {batch_idx+1}/{total_batches} "
f"({percent:.1f}%) "
f"Loss: {loss.item():.4f}",
end=""
)
print()
# =========================
# GENERATE
# =========================
@torch.no_grad()
def generate(model, prompt, stoi, itos,
max_new_chars=512,
temperature=0.8):
model.eval()
ids = [stoi.get(ch, 0) for ch in prompt]
x = torch.tensor(
[ids],
dtype=torch.long,
device=DEVICE
)
for _ in range(max_new_chars):
x_cond = x[:, -CONTEXT_SIZE:]
logits = model(x_cond)
logits = logits[:, -1, :] / temperature
probs = F.softmax(logits, dim=-1)
next_id = torch.multinomial(
probs,
num_samples=1
)
x = torch.cat(
[x, next_id],
dim=1
)
result = "".join(
itos[int(i)]
for i in x[0].tolist()
)
return result
# =========================
# MAIN
# =========================
def main():
if not os.path.exists(KNOWLEDGE_FILE):
print("knowledge.txt not found.")
return
with open(
KNOWLEDGE_FILE,
"r",
encoding="utf-8"
) as f:
text = f.read()
if len(text) < CONTEXT_SIZE + 2:
print("knowledge.txt too small.")
return
if os.path.exists(VOCAB_FILE):
with open(
VOCAB_FILE,
"r",
encoding="utf-8"
) as f:
stoi = json.load(f)
itos = {
int(v): k
for k, v in zip(
stoi.keys(),
stoi.values()
)
}
else:
stoi, itos = build_vocab(text)
save_vocab(stoi)
vocab_size = len(stoi)
encoded = [
stoi[ch]
for ch in text
if ch in stoi
]
dataset = CharDataset(
encoded,
CONTEXT_SIZE
)
loader = DataLoader(
dataset,
batch_size=BATCH_SIZE,
shuffle=True,
drop_last=True
)
model = GPTModel(vocab_size)
if os.path.exists(MODEL_FILE):
print("Loading existing model...")
model.load_state_dict(
torch.load(
MODEL_FILE,
map_location="cpu"
)
)
model = model.to(DEVICE)
params = count_parameters(model)
print("\n========================")
print(f"Device: {DEVICE}")
print(f"Vocabulary Size: {vocab_size}")
print(f"Model Parameters: {params:,}")
print("========================\n")
optimizer = torch.optim.AdamW(
model.parameters(),
lr=LEARNING_RATE
)
# Load optimizer state if it exists
if os.path.exists(OPTIMIZER_FILE):
print("Loading existing optimizer state...")
optimizer.load_state_dict(
torch.load(
OPTIMIZER_FILE,
map_location=DEVICE
)
)
for epoch in range(EPOCHS_PER_RUN):
print(
f"Epoch {epoch+1}/{EPOCHS_PER_RUN}"
)
train_epoch(
model,
loader,
optimizer
)
torch.save(
model.state_dict(),
MODEL_FILE
)
torch.save(
optimizer.state_dict(),
OPTIMIZER_FILE
)
# Create INT8 quantized version
quantized_model = torch.quantization.quantize_dynamic(
model.cpu(),
{nn.Linear},
dtype=torch.qint8
)
torch.save(
quantized_model.state_dict(),
"model_int8.pt"
)
# Move original model back to the selected device
model = model.to(DEVICE)
print("\nModel saved.")
print("Optimizer state saved.")
print("INT8 model saved as model_int8.pt")
while True:
prompt = input("\nYou: ")
if prompt.lower() in [
"quit",
"exit",
"q"
]:
break
reply = generate(
model,
prompt,
stoi,
itos,
max_new_chars=512
)
print("\nAI:")
print(reply)
if __name__ == "__main__":
main()
Only rich people can have kids now. Doesn't that prove that God doesn't exist.
No, it just means God likes rich people. That's why he made them rich.
God hates the poor.